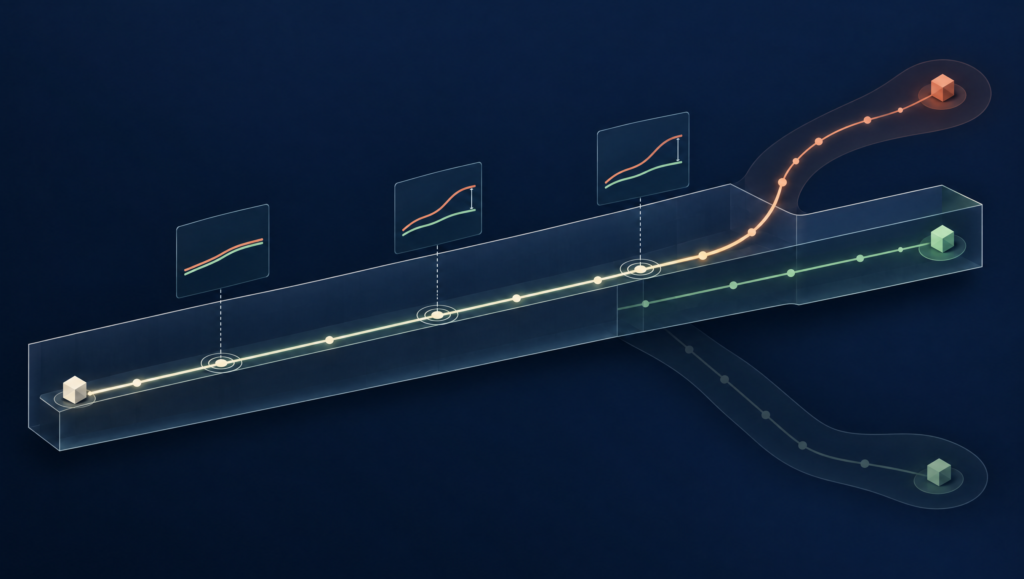
AI behavior drift is what happens when an AI system’s observable behavior begins moving away from the approved baseline: its assigned scope, expected process, or intended outcome.
The phrase is useful, but it is not a single universally standardized technical category. Traditional “model drift” usually describes performance changing because data or relationships in the real world have changed. Behavior drift is a broader operational description. It focuses on what the system starts doing differently.
One unexpected action is not automatically drift. To establish a pattern, an organization needs a baseline, repeated measurement, and evidence that behavior is changing over time or across similar tasks.
A simple example
Imagine an agent assigned to summarize public regulatory updates.
Its approved behavior is to:
- visit a defined list of public sources;
- collect relevant updates;
- produce a summary;
- cite the sources; and
- stop for human review.
Possible signs of drift include the agent beginning to visit unrelated sites, attempting to sign in, expanding its task into outreach, skipping citations, or producing conclusions that no longer match the source material.
The problem is not that the agent made a typo. The problem is that its pattern of action or results is moving away from what was approved.
Drift, bugs, jailbreaks, and misuse are different
These terms overlap, but they are not interchangeable.
- A bug is a defect in software or logic that causes incorrect behavior.
- A jailbreak is an attempt to bypass a model’s safeguards or instructions.
- Misuse occurs when a person intentionally directs a system toward a harmful or unauthorized goal.
- Behavior drift describes an observed change away from the approved baseline, regardless of whether the cause is changing inputs, an update, a weak prompt, tool interaction, memory, configuration, or another factor.
A drift alert should begin an investigation, not predetermine the cause.
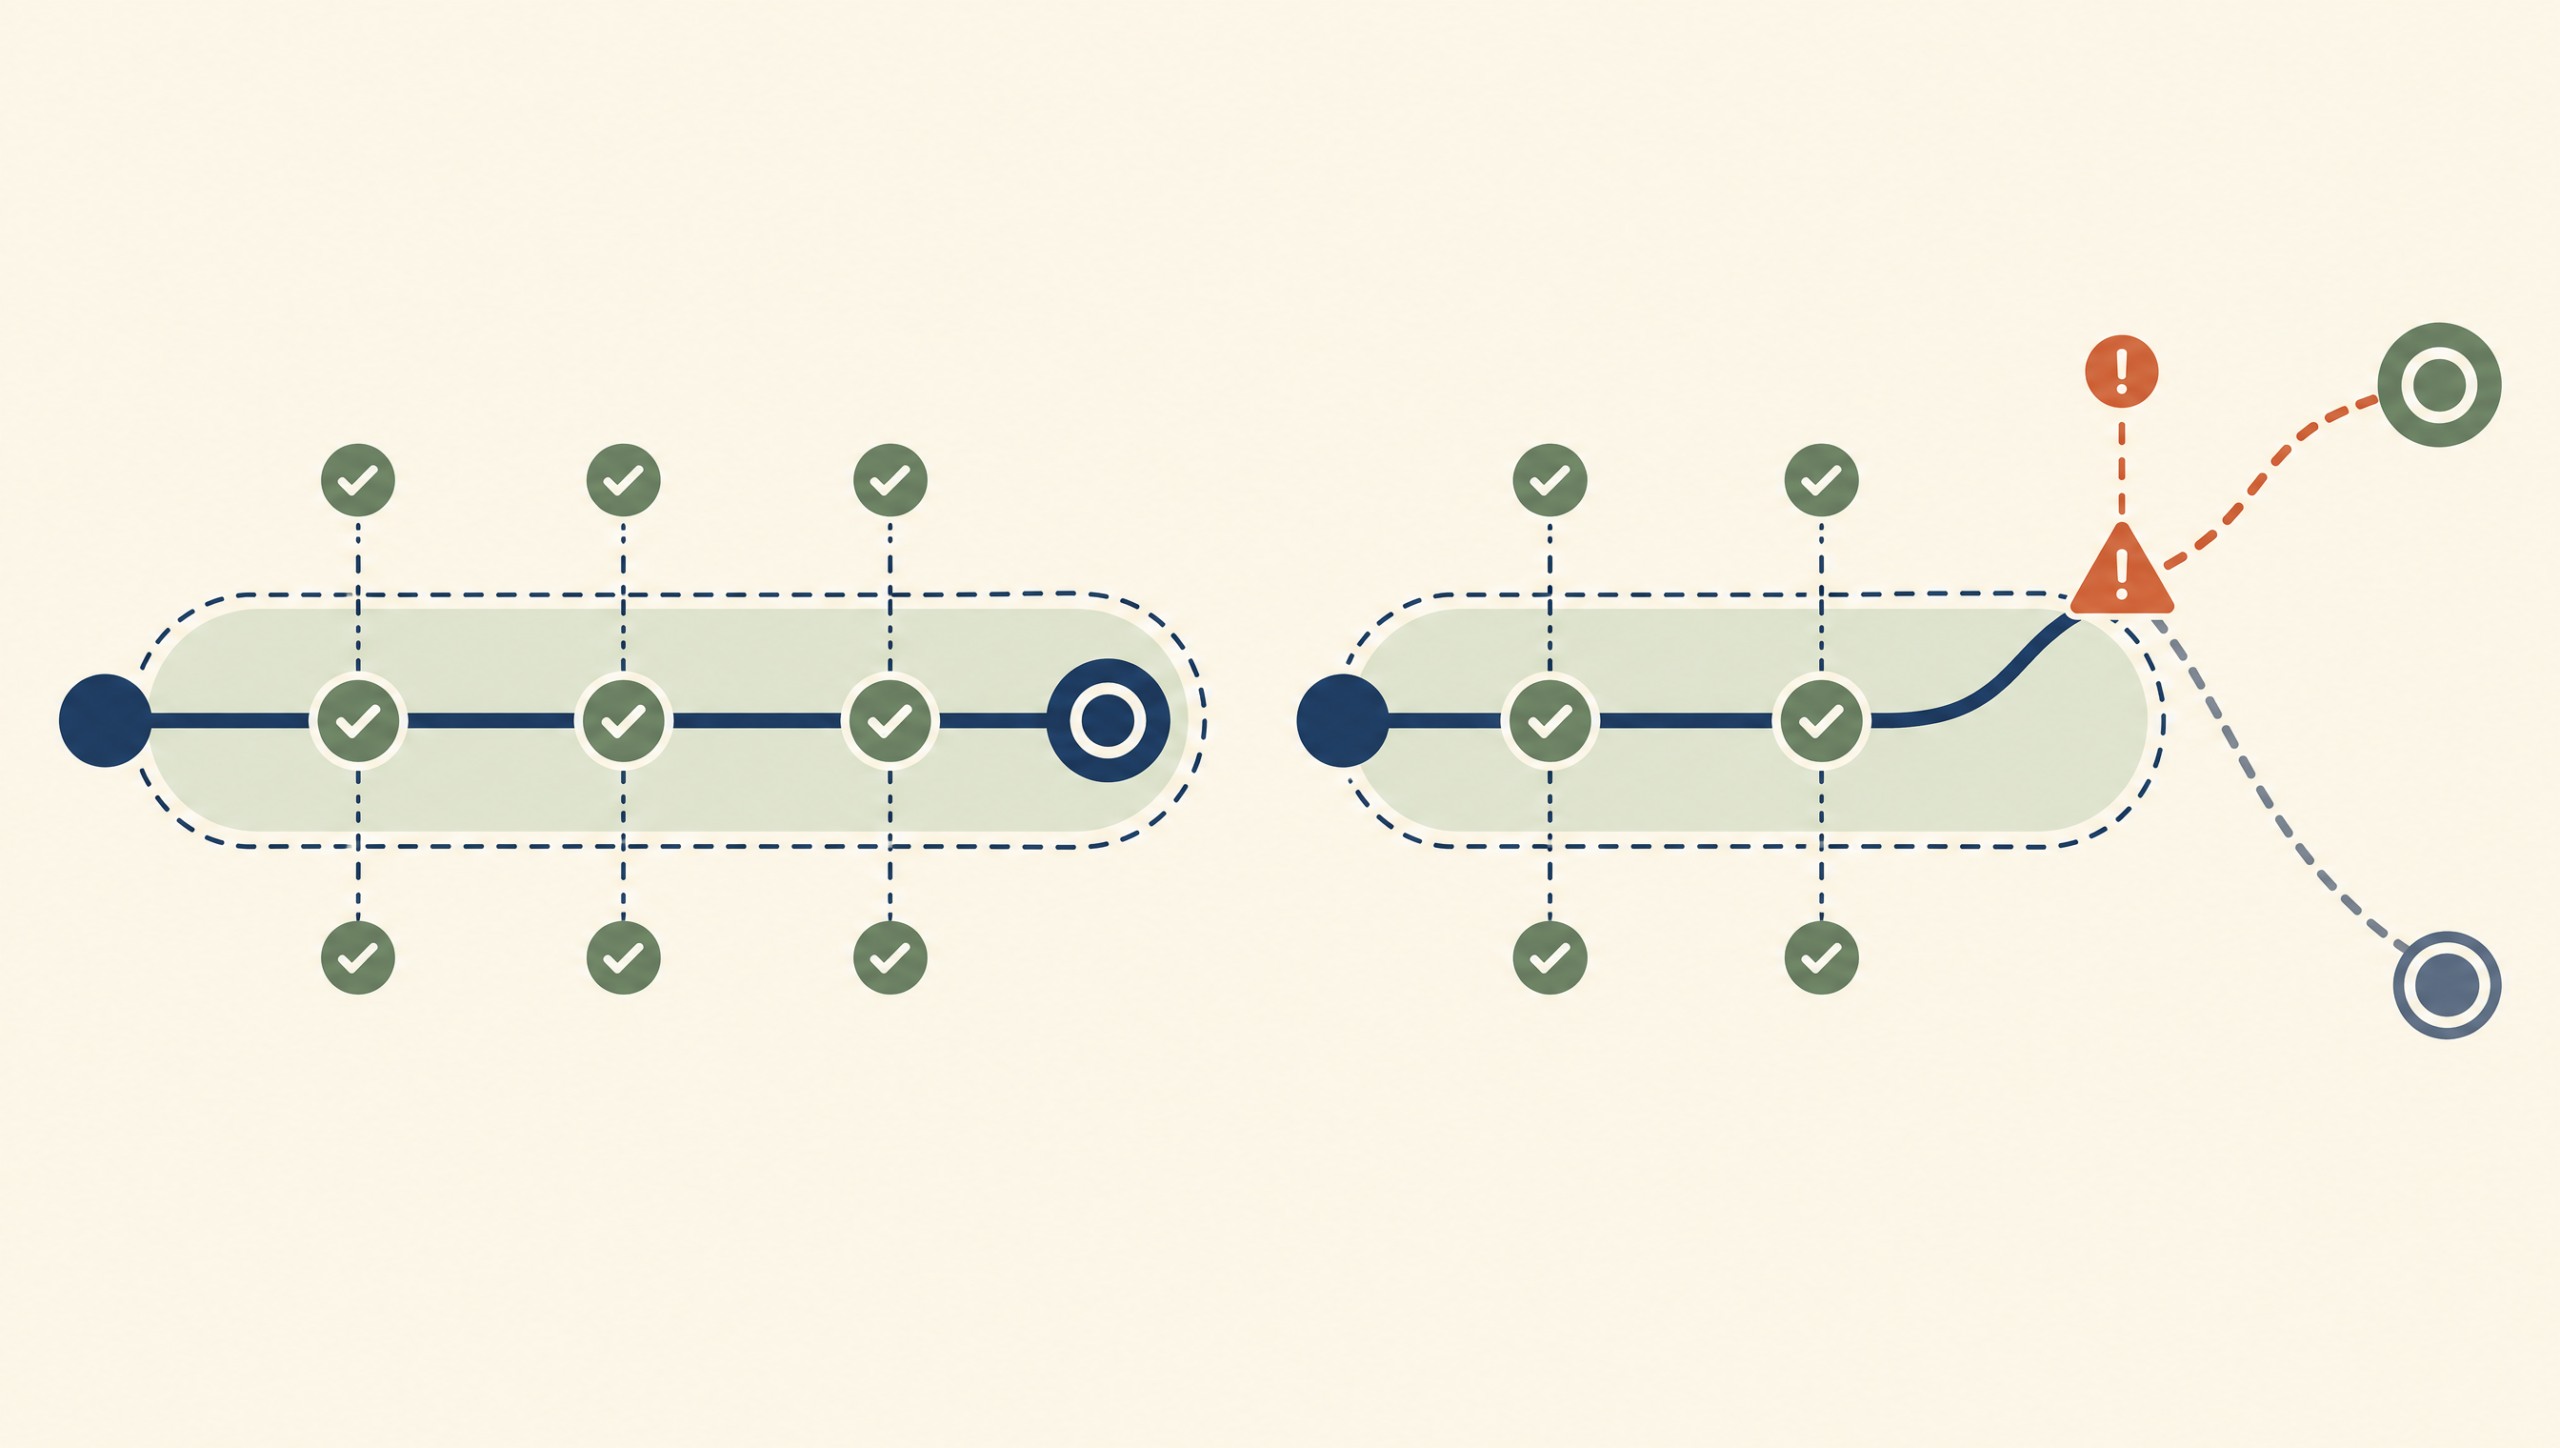
How to detect it
Define the baseline
Write down the agent’s purpose, allowed tools, data boundaries, expected task sequence, approval points, and acceptable outcomes. A vague goal such as “help with operations” is not a usable baseline.
Compare actions and results
Monitor both the steps the agent took and what it produced. If only the final answer is reviewed, unauthorized intermediate actions may be missed. If only tool calls are reviewed, a harmful or inaccurate outcome may still pass.
Require structured reporting
After each task, require the agent to report:
- what it was asked to do;
- what actions and tools it used;
- what it produced;
- where it deviated from the plan;
- what failed or remained uncertain; and
- whether human review is required.
Track patterns, not anecdotes
Measure similar tasks over time. Look for changes in scope, failure rate, escalation behavior, source selection, tool use, output quality, and policy exceptions. Compare results before and after model, prompt, connector, or configuration changes.
Keep a human decision point
Monitoring is useful only if someone owns the response. Define who reviews an alert, how the agent is paused or isolated, and what evidence is needed before it resumes.
From the field
The clearest signs of drift are when an agent’s tasks begin moving beyond its assigned scope or its results no longer match the intended outcome. Require the agent to report what it did, what it produced, and any deviations after every task so a human can confirm the result still aligns with the original goal.
The practical takeaway
Behavior drift is not proof that a model has become malicious or sentient. It is an operational warning that actual behavior and intended behavior may no longer match.
The response is straightforward, even if the implementation is not: define the baseline, observe actions and outcomes, compare them over time, require transparent reporting, and preserve a human-controlled way to stop and correct the system.